Call every model through one API, inside the country.
The Inference Gateway is one API in front of Aleria's own models and open models, all running in the country. It checks each call's key and limit, sends it to the model that fits, and logs it.
- 1 API
- for Aleria's own models and open models
- 0 calls
- to a model outside the country
- 1 key
- for each team, app or expert, with its own limit
- 1 log
- of every call, the model that answered and its cost
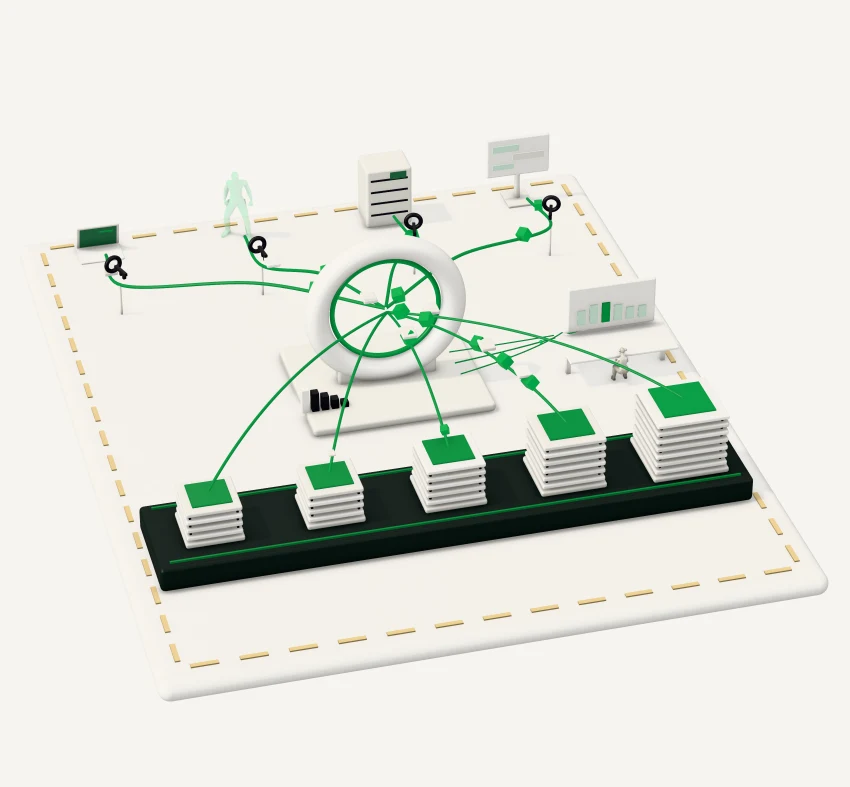
A bank's tool moves back into the country.
Hassan's team built a tool that summarizes credit files, on a model API hosted abroad. Compliance asked them to stop.
They point the tool at the Inference Gateway and change the key. The same code now calls models that run in the country.
Each team gets its own key and its own monthly limit. Every call, the model that answered it and what it cost are in one log for the auditors.
- Keyrisk-team · 82% of this month's limit
- CallAleria Reason · 3,120 tokens · 1.8 s
- CallOpen model · documents · 8,400 tokens
- FailoverA server failed · the call moved to the next one
- CallOpen model · documents · 7,950 tokens
- Log412 calls today · 0 outside the country
How it works, in four steps.
- Get a key
Create a key for each team, app or expert. The key tells the Gateway who is calling, and it carries its own limit.
- Call one API
Send requests in the common chat-completions format, from the CLI, or through the MCP server, the open standard many AI tools use to reach apps and data.
- The gateway routes
Each call goes to the model that fits it. If a server fails, the call moves to another, and the answer stays in the country.
- See what happened
Usage, cost and the log of every call in one console, by team, app and expert.
The model register, every model in one list.
Each model is listed with what it is for, its languages, where it runs and its licence. Your administrator enables the ones your organization uses.
| Model | For | Languages | Runs | Licence |
|---|---|---|---|---|
| Aleria Reason | Reasoning, analysis, drafting | Arabic, English | In the country | Aleria |
| Open model · documents | Reading and drafting documents | Multilingual | In the country | Open weights |
| Open model · code | Writing and reviewing code | Multilingual | In the country | Open weights |
| Aleria Speech | Speech recognition and read-aloud | Arabic, English and others | In the country | Aleria |
| Aleria Vision | Video AI events | Images and video | Edge or data center | Aleria |
What stays in your hands.
- Which models people use
- Your administrator enables the models for your organization. In Aleria OS, people pick one from the model picker for each request.
- Who can call what
- Each key belongs to a team, an app or an expert, with its own limit.
- Where calls run
- In an Aleria data center in the country, or on your servers. No call goes to a model abroad.
- What is recorded
- Every call: who made it, which model answered, and what it cost.
- What it costs
- Per million tokens, per model, in AED or USD. On your servers, on your own billing.
- What runs where
- Language, speech and vision models, each in the model register with where it runs and its licence.
Questions customers ask first.
Is it compatible with the tools we use?
The API follows the common chat-completions shape, so most SDKs and frameworks work by changing the base URL and the key.
Which models are behind it?
Aleria's own models and selected open-weight models, each listed in the model register with its licence and where it runs.
Does any call go to a model abroad?
No. Every model runs in an Aleria data center in the country, or on your servers.
How is it billed?
Per million tokens, per model, in AED or USD. On your servers, with your own billing.